Attention is all you need
The Transformer is a sequence-to-sequence (transduction) model that replaces sequence-aligned RNNs and convolutions with attention mechanisms. It uses self-attention to relate positions within a sequence and cross-attention to connect input and output sequences, enabling direct modeling of long-range dependencies and highly parallel computation.
Recurrent models typically factor computation along the symbol positions of the input and output sequences.
RNNs process a sequence one position/token at a time, rather than processing all positions independently at once. For example, take:
"I love pizza"
The input has 3 symbol positions:
I → love → pizza
1     2      3
A recurrent model computes something like:
h₁ = f(I, h₀)
h₂ = f(love, h₁)
h₃ = f(pizza, h₂)
So computation is factored along the sequence positions.
This inherently sequential nature precludes parallelization within training examples, which becomes critical at longer sequence lengths, as memory constraints limit batching across examples.
this is why RNNs are hard to train efficiently, especially for long sequences.
RNNs have to process each sequence position one after another. This prevents GPUs from fully parallelizing a single sequence. The problem gets worse for long sequences, because long sequences also consume more memory, forcing us to use smaller batches.
Longer sequence → more memory per example → fewer examples fit in a batch → smaller batch size.
RNN:
x₁ → x₂ → x₃ → x₄ → x₅
     sequential 🚶

Transformer:
x₁   x₂   x₃   x₄   x₅
 ↘   ↓ ↙  ↓  ↘  ↓
   attention
parallel ⚡
sequence modelling : learning from data where the order of elements matters.
a sequence is simply :
x₁ → x₂ → x₃ → x₄ → ...
Text:
I → love → pizzaSpeech: audio frames over time
Stock prices: price₁ → price₂ → price₃
Time series: temperature₁ → temperature₂ → ...
DNA:
A → C → G → T
The model learns relationships between elements in that sequence.
transduction models : taking one sequence and transforming it into another sequence.
Think:
Input sequence
      ↓
    Model
      ↓
Output sequence
for example, machine translation:
English:
"I love pizza"
       ↓
French:
"J'aime la pizza"
both sides are sequences, but they don't necessarily have the same length.
About transformer :
trained for as little as 12 hours on eight P100 GPUs.
Tesla P100 was a serious data-center/HPC GPU, not a consumer gaming GPU. It launched in 2016 as part of NVIDIA's Pascal generation.
| Spec | Tesla P100 |
|---|---|
| CUDA cores | 3,584 |
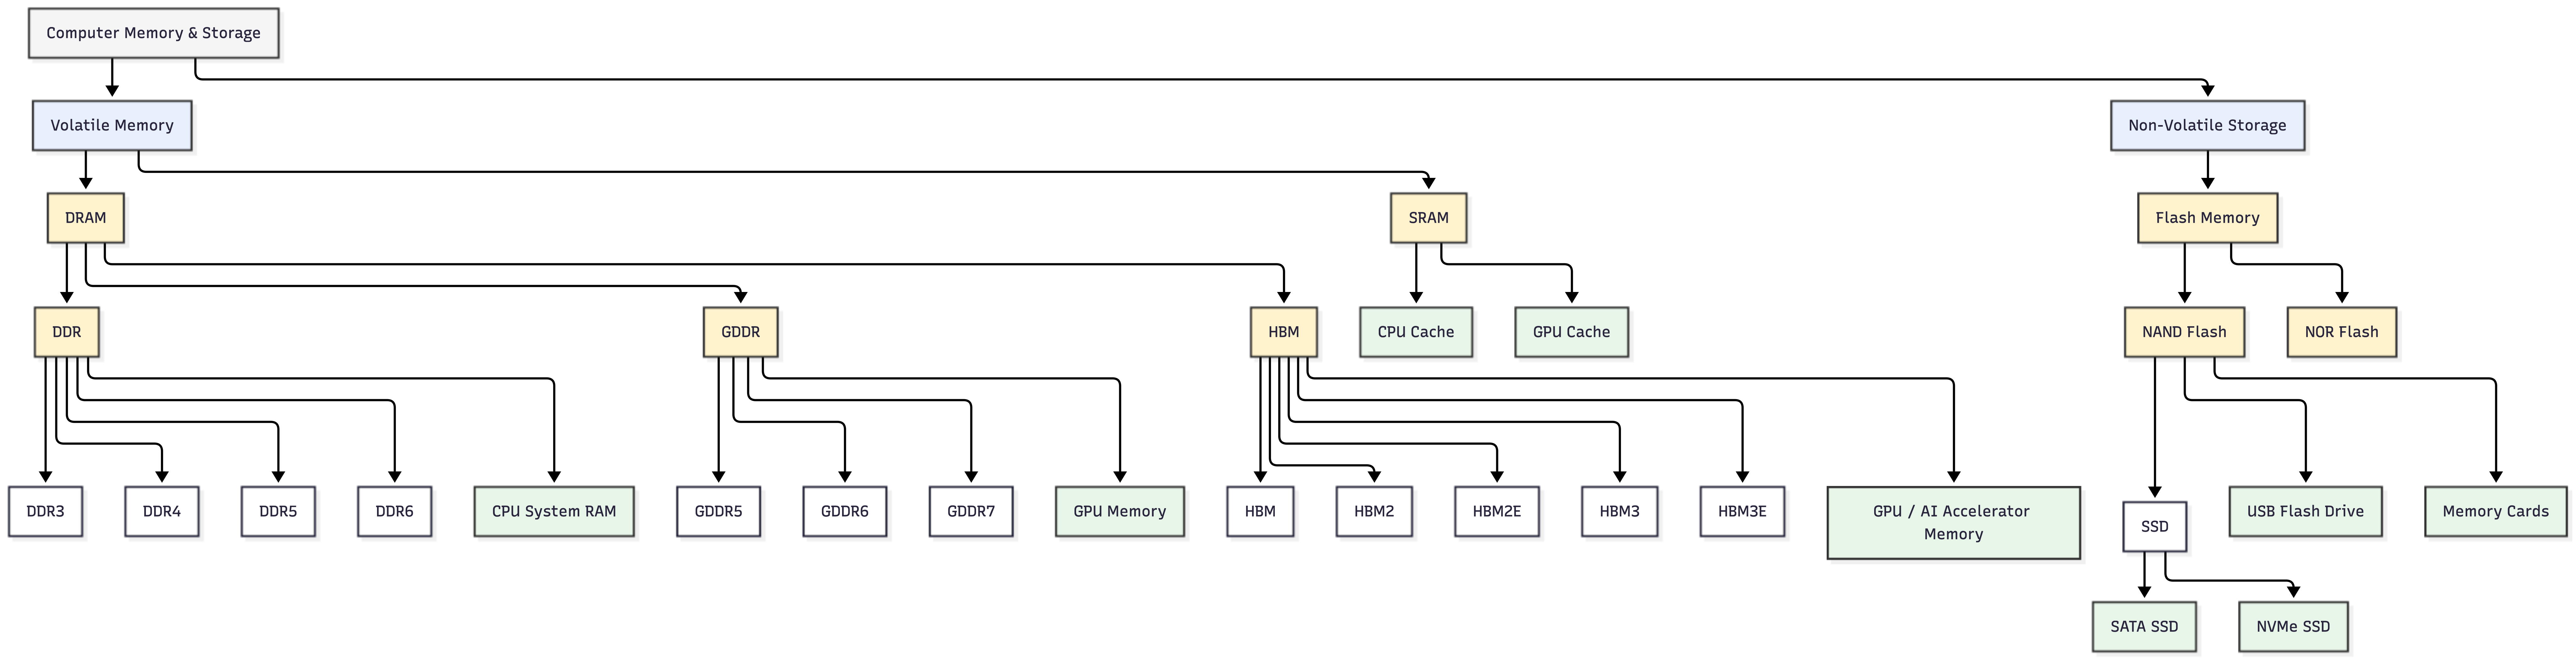
| GPU memory | 16 GB HBM2 |
| Memory bandwidth | 732 GB/s |
| FP32 | 9.3 TFLOPS PCIe / 10.6 TFLOPS NVLink |
| Power | 250 W PCIe / 300 W NVLink |
| Architecture | Pascal |
| Intended use | AI + scientific/HPC workloads |
FP32 (32-bit floating-point numbers) performance : how quickly the GPU can perform 32-bit floating-point calculations
TFLOPS : trillion floating-point operations per second.
PCIe : Peripheral Component Interconnect Express, high-speed connection used to connect components inside a computer.
NVLink : NVLink is NVIDIA's high-speed GPU interconnect.
Convolutional Neural Networks ( CNNs ) :
a specialized type of neural network designed to understand spatial patterns
we can think of patterns like these :
| Pattern | What it means | Commonly handled by |
|---|---|---|
| Spatial | Where things are and their local arrangement | CNNs |
| Temporal | How something changes over time | RNNs, LSTMs, Transformers |
| Sequential | Relationships based on order | RNNs, Transformers |
| Hierarchical | Simple features combine into complex ones | CNNs, deep networks |
| Local | Relationships between nearby elements | CNNs, attention |
| Global | Relationships between distant elements | Transformers, attention |
| Relational | How entities relate to each other | Transformers, GNNs |
| Graph/structural | Connections between nodes | GNNs |
| Frequency | Patterns in frequency rather than position | CNNs, Fourier-based methods |
before transformer, nn architectures for sequence processing :
Extended Neural GPU
Neural GPU was designed to process sequences using convolution-like operations. It used recurrent computation plus convolutional operations to process sequences.
Extended Neural GPU improved the original architecture to handle longer sequences and tasks such as algorithmic/sequence transformations.
ByteNet
was a neural architecture for seq-to-seq tasks, its important idea was dilated convolutions. This lets the network look at a larger context without requiring as many layers.
used for : machine translation, language modeling and text generation
ConvS2S
Convolutional Sequence to Sequence, alternative to RNN for sequence-to-sequence problems. made training more parallelizable than traditional RNNs.
used for : machine translation
Q. If information at position A needs to affect position Z, how many computational steps does the model need?
A. linear fo ConvS2S and logarithmic for ByteNet
Transformer : constant path length
Constant number of ops means constant path length O(1) between any two positions.
token can directly attend to another token, regardless of distance.
It does not mean total Transformer computation is O(1).
attention combines information from multiple positions using weighted averaging :
Output = 0.2×A + 0.5×B + 0.3×C
Benefits
short path : easier long-range information flow and gradient/credit assignment
parallel computation : all token relationship can be computed together during training and much better CPU / GPU utilisation.
Problems with Transformers
Problem 1 : transformers connects distant positions directly
one attention operations mixes information : information isn't literally destroyed, but different relationships can become mixed together.
so how do we preserve different relationships ? multi-head attention mechanism
Instead of
what should this token attend to ?we ask it multiple times using different learned projections.each head has its own learned parameters, so each can learn to focus on different relationships. eg.: ( this is what heads can learn, they aren’t hardcoded rules )
Head 1 → grammatical relationship

Head 2 → nearby relationship

Head 3 → positional/local relationship

Head 4 → another long-range relationship
Instead of forcing all these relationships into one attention pattern, we have multi attention patterns, then the outputs from all heads are combined. so the model gets a richer representation containing different kinds of relationships at same time.
the entire chain
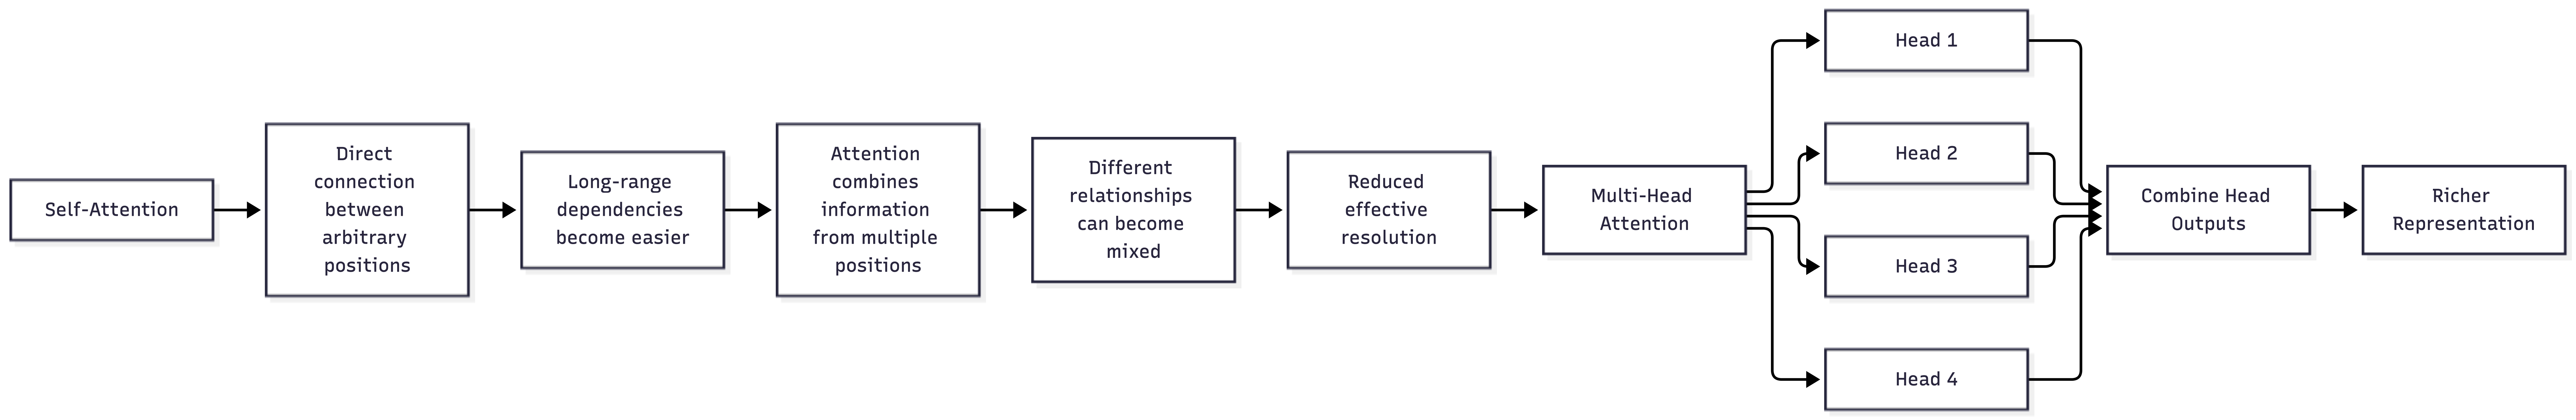
Each head has separate learned parameters, and during training, different heads may naturally specialize in different relationships.
Self Attention
Self-attention, sometimes called intra-attention, is an attention mechanism relating different positions of a single sequence in order to compute a representation of the sequence.
self-attention allows each position to look at other positions in the same sequence.
eg.: when processing eating in The dog is eating
"The"   → 0.05
"dog"   → 0.60
"is"    → 0.10
"eating"→ 0.25
so the representation of "eating" is computed using information from the other words, that's self-attention.
query and the information ( Q, K and V ) being attended to come from the same sequence. every token can attend to other tokens within same seq.
use cases : reading comprehension, abstractive summarisation, textual entailment and learning task-independent sentence representations.
cross-attention
Imagine two different seq : The dog is eating → Le chien mange
decoder's french tokens can attend to the english encoder seq.
french seq query → english seq key/value
that's cross-attention, because attention is happening between two different sequences.
e2e memory networks are based on a recurrent attention mechanism instead of sequence-aligned recurrence & have been shown to perform well on simple-language question answering and language modeling tasks.
memory network is an architecture that gives the model an explicit memory.
recurrent attention mechanism : recurrence happens as we move through the seq.
sequence-aligned recurrence : recurrence happens by repeatedly attending to mem.